Best Local LLMs for Mac by RAM (16GB to 128GB)
Find the best local LLM for your Mac by RAM tier. Model recommendations, quant sizes, KV cache math, and token benchmarks for 16GB, 32GB, 64GB, and 128GB.
Choose the right hardware for AI workloads. Guides on GPUs, TPUs, AI PCs, edge computing, and on-device inference for optimal performance.
Find the best local LLM for your Mac by RAM tier. Model recommendations, quant sizes, KV cache math, and token benchmarks for 16GB, 32GB, 64GB, and 128GB.
Turn your Mac mini into an always-on home AI server. Headless macOS setup, launchd configuration, Tailscale remote access from phone/laptop, and Open WebUI.
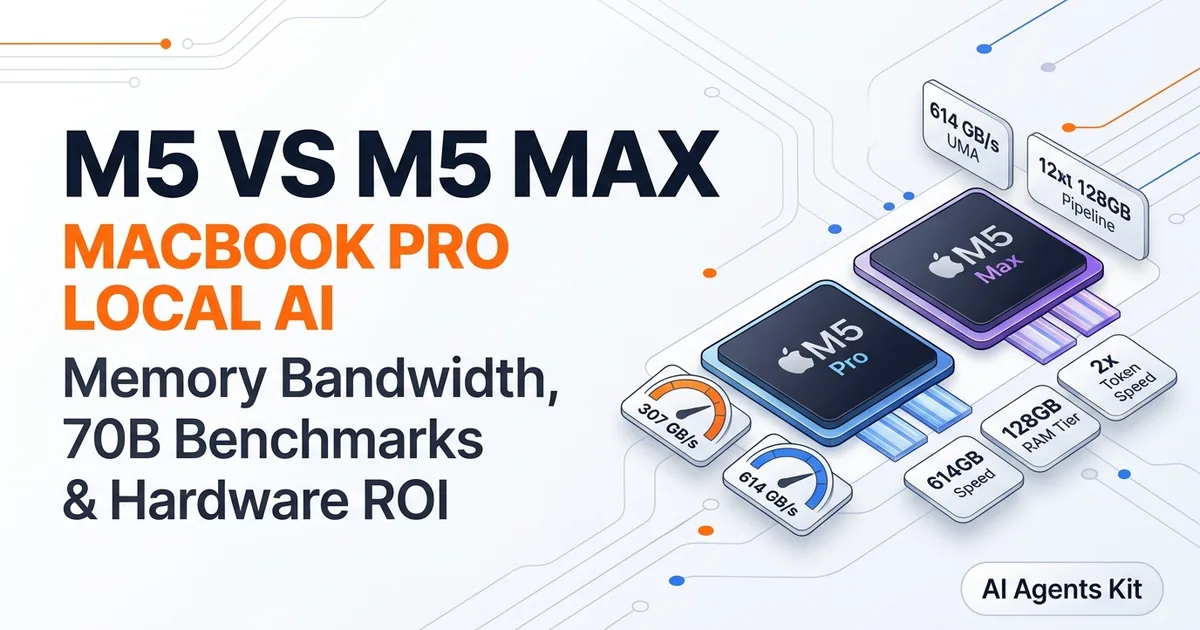
Compare MacBook Pro M5 vs M5 Max for local AI. Benchmarks, memory bandwidth specs (307 vs 614 GB/s), token speeds for 70B models, and developer ROI.
Boost Ollama speeds on Apple Silicon with MLX. Learn environment variable tuning, memory cache optimization, and benchmarks across M-series chips.
Discover the best local LLM for coding matched to your GPU VRAM tier. Compare Qwen 2.5 Coder, DeepSeek Coder, KV cache math, and VS Code Continue setups.
Discover how Intel Arc runs local AI in 2026. Compare Arc A770 16GB and B580 Battlemage benchmarks, OpenVINO, IPEX-LLM, and budget RTX trade-offs.
Learn how to run local LLMs on a gaming laptop. Compare mobile RTX GPUs, thermal throttling, TGP limits, and layer offloading strategies to system RAM.
Discover RTX 5090 local AI performance. Compare 32GB GDDR7 tokens per second across 8B, 14B, 32B, and 70B models, power limits, and dual 3090 trade-offs.
Evaluate whether a used RTX 3090 is worth buying for local AI in 2026. Compare 24GB VRAM value, thermal pads, power demands, and RTX 4070 Ti Super trade-offs.
Best local LLMs for RTX 4060, RTX 3070, and RTX 5060 in 2026. Compare 8GB VRAM fit, GDDR7 token speeds, Ollama settings, and realistic 8B models.
Compare NVIDIA and AMD GPUs for AI workloads in 2026. Updated specs, real pricing, CUDA vs ROCm analysis, and practical buying recommendations for local AI.
Complete guide to running AI locally on Mac with Apple Silicon. Ollama setup, MLX framework, M5 hardware advice, Llama 4 support, and model recommendations for M1-M5 chips.
What is an AI PC and do you actually need one in 2026? Get the data-backed truth about NPUs, Copilot+ requirements, chip comparisons, best picks by budget, and a clear buying framework for students, creators, and professionals.
Compare the best GPUs for running AI locally in 2026. Discover VRAM tiers, memory bandwidth benchmarks, Ollama models, and NVIDIA vs AMD trade-offs.
Learn how to run local LLMs, Stable Diffusion, and computer vision on Raspberry Pi. Complete setup guide with Ollama, Piper TTS, and ONNX Runtime.
Calculate exactly how much VRAM you need for AI models. Complete 2026 guide with requirements for Llama, Mistral, and more. VRAM tables and formulas included.
Cloud vs local AI comparison covering hardware costs, inference latency, break-even thresholds, privacy compliance, and hybrid multi-agent architectures.
A comprehensive guide to building your own AI workstation. Choose parts for every budget tier, from entry-level to extreme, with specific recommendations.
Run local AI models on Raspberry Pi 5. Complete guide to Ollama, Hailo-8L NPU accelerators, computer vision, and optimized edge AI hardware pipelines.
Learn what edge AI is, why running AI locally matters for privacy and speed, and how on-device processing works with practical implementation examples.
Why is your AI slow? Learn what affects inference speed and how to optimize. Complete guide to GPU bottlenecks, quantization impact, and performance tuning.
This AI Hardware archive brings together explainers, guides, and working examples on Local LLM, AI Hardware, Apple Silicon, Hardware, Ollama, and VRAM. Choose the right hardware for AI workloads. Guides on GPUs, TPUs, AI PCs, edge computing, and on-device inference for optimal performance.
Use this page when you want a solid starting point, a short list of strong next reads, or a quicker way to compare related ideas before you open a more specific article.
If you are new to this topic, start with Best Local LLMs for Mac by RAM (16GB to 128GB), Mac mini as a Home AI Server, and MacBook Pro M5 vs M5 Max for Local AI. Together, those articles give you a clear overview, a few practical examples, and a better sense of where to go next.
Find the best local LLM for your Mac by RAM tier. Model recommendations, quant sizes, KV cache math, and token benchmarks for 16GB, 32GB, 64GB, and 128GB.
Turn your Mac mini into an always-on home AI server. Headless macOS setup, launchd configuration, Tailscale remote access from phone/laptop, and Open WebUI.
Compare MacBook Pro M5 vs M5 Max for local AI. Benchmarks, memory bandwidth specs (307 vs 614 GB/s), token speeds for 70B models, and developer ROI.