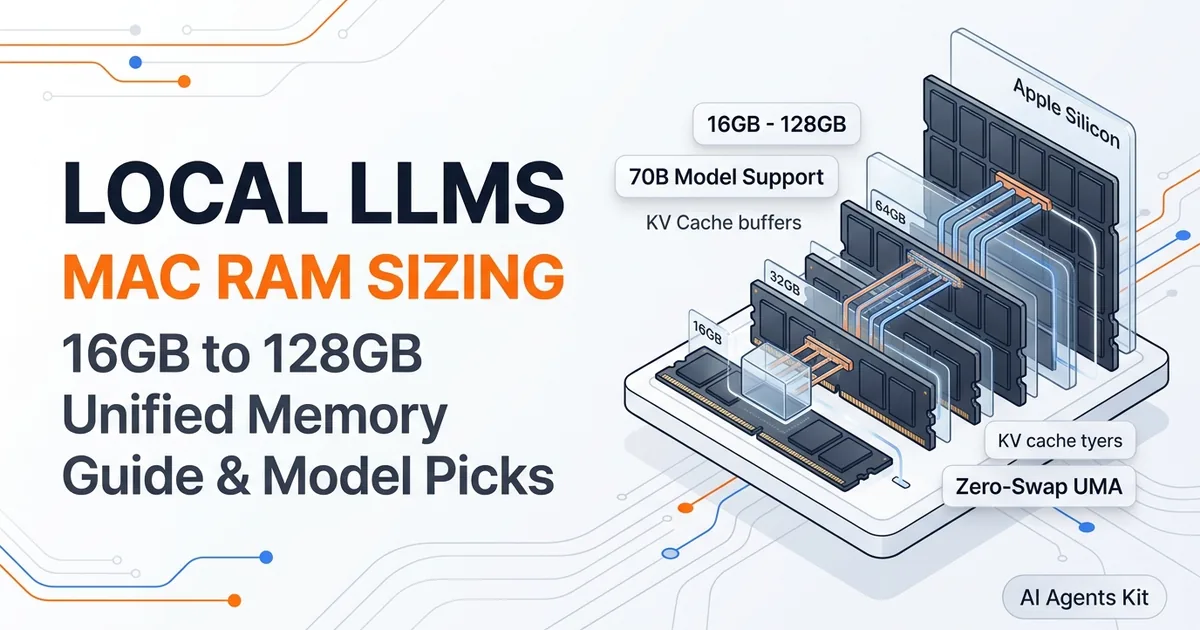
Best Local LLMs for Mac by RAM (16GB to 128GB)
Find the best local LLM for your Mac by RAM tier. Model recommendations, quant sizes, KV cache math, and token benchmarks for 16GB, 32GB, 64GB, and 128GB.
Mac AI Apple Silicon Local LLM
Tutorials, code snippets, and insights on AI agents, LLMs, and developer tools.
Find the best local LLM for your Mac by RAM tier. Model recommendations, quant sizes, KV cache math, and token benchmarks for 16GB, 32GB, 64GB, and 128GB.
Set up a private local coding assistant in VS Code on Mac. Configure Ollama with Continue and Cline, dual-model autocomplete, and Qwen 2.5 Coder.
Turn your Mac mini into an always-on home AI server. Headless macOS setup, launchd configuration, Tailscale remote access from phone/laptop, and Open WebUI.
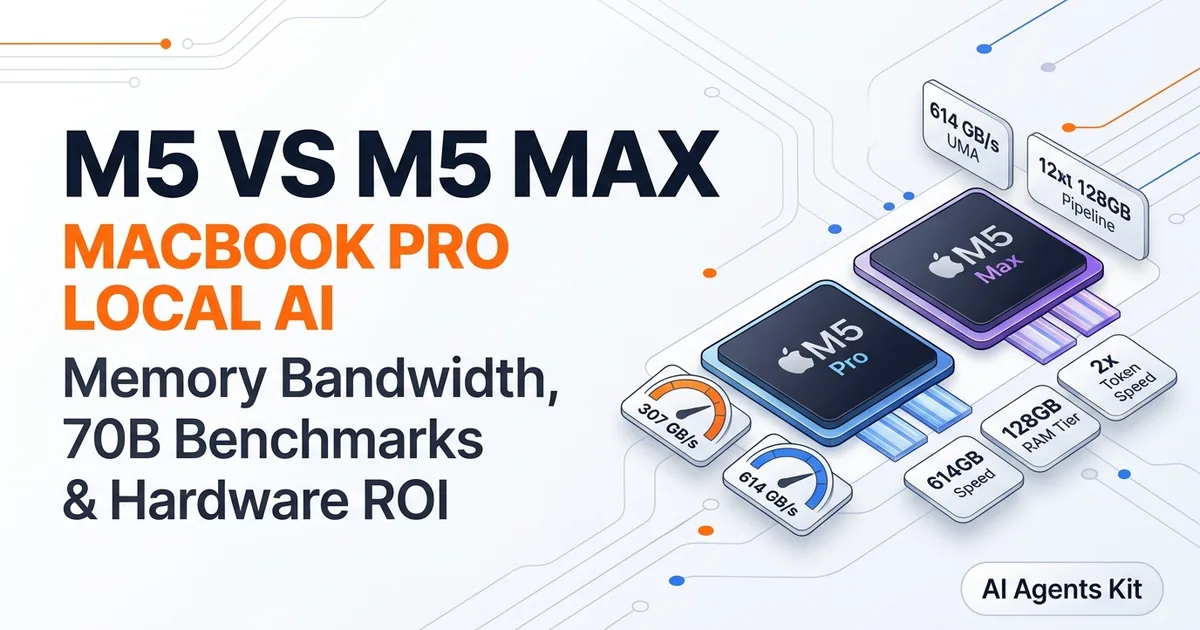
Compare MacBook Pro M5 vs M5 Max for local AI. Benchmarks, memory bandwidth specs (307 vs 614 GB/s), token speeds for 70B models, and developer ROI.
Compare Apple MLX vs llama.cpp on Apple Silicon. Benchmarks, token generation speeds, memory usage, GGUF vs MLX quants, and fine-tuning trade-offs.
Boost Ollama speeds on Apple Silicon with MLX. Learn environment variable tuning, memory cache optimization, and benchmarks across M-series chips.
Discover the best local LLM for coding matched to your GPU VRAM tier. Compare Qwen 2.5 Coder, DeepSeek Coder, KV cache math, and VS Code Continue setups.
Learn how to build a dual-GPU setup for local LLMs. Configure PCIe bifurcation, power supply sizing, llama.cpp layer splitting, and vLLM tensor parallelism.
Discover how Intel Arc runs local AI in 2026. Compare Arc A770 16GB and B580 Battlemage benchmarks, OpenVINO, IPEX-LLM, and budget RTX trade-offs.
Learn how to run local LLMs on a gaming laptop. Compare mobile RTX GPUs, thermal throttling, TGP limits, and layer offloading strategies to system RAM.
Discover RTX 5090 local AI performance. Compare 32GB GDDR7 tokens per second across 8B, 14B, 32B, and 70B models, power limits, and dual 3090 trade-offs.
Evaluate whether a used RTX 3090 is worth buying for local AI in 2026. Compare 24GB VRAM value, thermal pads, power demands, and RTX 4070 Ti Super trade-offs.
Try adjusting your search terms
Use the archive when you want the fastest path into a topic. It brings together recent posts, foundational explainers, and category entry points so you can decide whether to start with a tutorial, a comparison, or a broader overview before you dive deeper.